High-Performance Serving Framework for LLMs and Multimodal Models

SGLang powers fast, scalable inference for large language and multimodal models.

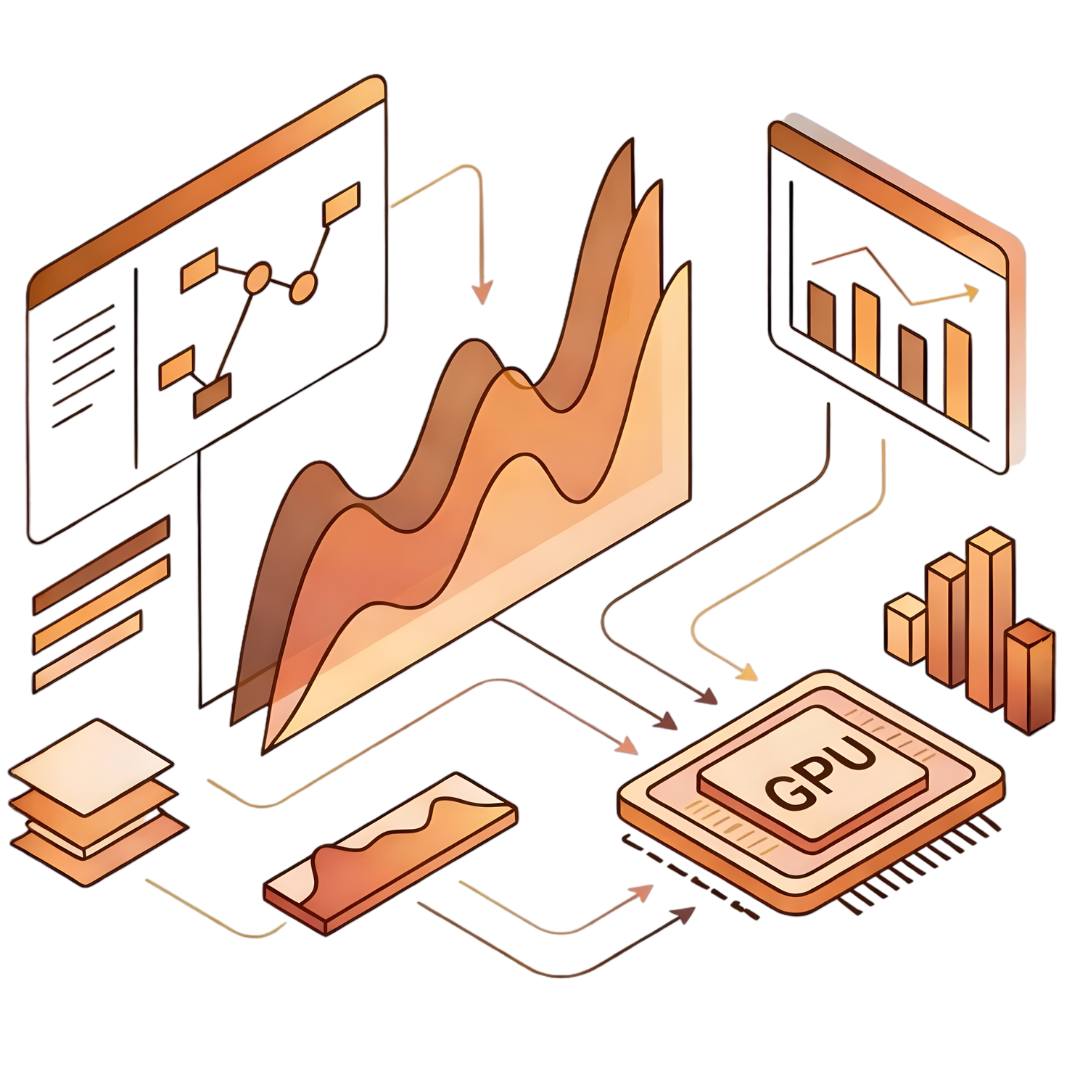
SGLang Data Processing Architecture
Google
Intel
RadixArk
NVIDIA
Meta
AMD
AWS
Crusoe
Inco AI
LanceDB
Modal
Nebius
Snowflake
ai&
Arcee AI
Liquid AI
Microsoft AI
Runpod
Samsung
DeepInfra
Eigent
Harmonic
HUD
Netpreme
PaleBlueDot AI
Palo Alto Networks
SF Compute
Yotta Labs
Applied Compute
MiniMax
Ornith
Periodic Labs
SemiAnalysis
SGLang Summit 2026, presented by LMSYS

Join us in San Francisco

Open foundations for the next era of AI.

November 12–13, 2026
Fort Mason, San Francisco

Join the Summit

Production-Grade Inference

Built for large-scale deployments, delivering reliable, low-latency, high-throughput serving from a single accelerator to distributed clusters.

Model & Hardware Flexibility

Supports large language, vision-language, and diffusion models for text, multimodal understanding, and image and video generation across diverse hardware platforms.

Advanced Optimizations

Incorporates disaggregated prefill/decode, speculative decoding, parallelisms, a zero-overhead scheduler, and optimized GPU kernels.

Get Started in Seconds

Select your preferences and run the deployment command. SGLang is designed to be easy to install and deploy.

1

Install via pip or docker

The easiest ways to get started.

2

Launch the server

Start the server with a single command pointing to your model.

3

Query the API

Use standard OpenAI-compatible endpoints to interact with your model.

Build
Platform
Package
CUDA Version

Run this Command:
uv pip install sglang sglang-kernel \
  --extra-index-url https://sgl-project.github.io/whl/cu129/ \
  --extra-index-url https://download.pytorch.org/whl/cu129 \
  --index-strategy unsafe-best-match

Broad Model & Hardware Support

A single engine that runs across various models and hardware.

Supported Hardware

NVIDIA GPUs
AMD GPUs
Google TPU
CPU Servers
Ascend NPUs
XPU

Supported Models

DeepSeek
Qwen
GPT-OSS
Llama
Mistral
GLM

Release Notes

v0.5.22Latest

950 PRs·245 contributors·69 new contributors

Highlights

  • DeepSeek-V4.1 gets up to 2.3x more throughput per GPU on H200, and now runs on AMD MI350X / MI355X with up to 1.9x throughput from DSpark.

  • Qwen3.8-Flash-Next decodes 12% faster on B200, and GLM-5.3-Flash with DFlash 10% faster on B300.

  • MiMo-V2.6-Pro gets 1.85x decode throughput with DFlash on B300.

+7 more highlights

Join the Community

From first-time users to teams debugging complex deployments, the community is open to everyone.

For enterprise adoption, deployment, technical consulting, sponsorship, or partnerships, contact sglang@lmsys.org.